Last updated: September 24, 2026. This article separates today's available functions from plausible scenarios for 2027. Product names and platform status are accurate as of the update date.
In recent years, for most companies, interaction with artificial intelligence began in a chat window. The user asked a question, and the model generated a response. AI agents take this interaction further: they receive a goal, consult data, use software tools, and can execute multiple steps to achieve a result.
The difference is not just in the interface. An agent can decide which information is missing, what tool needs to be used, whether the result is sufficient, and when to stop or request human approval. However, this autonomy must have clear boundaries. A useful agent for a company is not a “digital employee” left to act unsupervised, but a managed software system with clearly defined access, responsibilities, and success criteria.
In this guide, we explain what an AI agent is, how it is built, how it can be specialized, what implementation models exist, and who is responsible for managing it. We also look ahead to 2027, when personal and organizational agents may take on more tasks, request quotes, or initiate purchases within limits set by people.
Language models have become more capable of handling complex instructions, documents, images, and software tools. At the same time, current platforms now offer components for memory, evaluation, observability, human approvals, and integration with external applications.
These components change the practical question for a company. It’s no longer just about whether a model can draft accurate text, but whether a system can complete a defined activity: prepare a quote, update a ticket, check an order, compare information, or follow a process through to a stopping condition.
However, current interest does not validate every promise of autonomy. For predictable tasks with fixed steps, classic automation may be simpler, cheaper, and safer. An agent becomes easier to justify when the path can’t be fully described in advance but the objective, tools, and outcome can still be controlled.
In 2026, the approach with the strongest operational support is to use agents in well-defined processes, with known tools, minimal permissions, and explicit approvals.
For 2027, a plausible scenario is more frequent use of personal and organizational agents to request quotes, book services, or prepare purchases within mandates and budgets set by people.
What We’re Not Assuming: general autonomy, business decisions without accountability, eliminating human verification, or a system that “learns by itself” without a controlled process.
There isn’t yet a single definition used identically by all providers. An operational definition, fit for a business project, is the following:
An AI agent is a software system in which an artificial intelligence model decides—within set boundaries—which steps to take and which tools to use to accomplish a goal on the user’s behalf.
OpenAI describes agents as systems that independently complete tasks for users, with the model driving the flow of execution. Anthropic summarizes the mechanism as the autonomous use of tools by a model, within a loop.
An agent can:
Commercial names vary across providers, and boundaries aren’t absolute. The useful distinction is who drives the process and how much freedom the system has to choose the next step.
System Type | Who Determines the Steps | Role of the Model | Example |
|---|---|---|---|
Classic Automation | The programmer, via explicit rules | May be absent entirely | If the invoice is overdue, send a standard message |
Workflow with LLM | The code determines the route | The model performs certain steps | Extracts data, classifies the request, then fills in a template |
Assistant or copilot | The user drives the process | Recommends and prepares results | Drafts an offer based on the provided information |
AI agent | The model selects steps and tools within defined limits | Oversees the execution of a task | Checks data, asks for clarification, prepares the offer, and requests approval |
Multi-agent system | Multiple agents coordinate or transfer tasks | Each agent has a distinct role | One agent analyzes the request, another checks stock, and a coordinator brings the results together |
A chatbot that only answers questions does not automatically become an agent. No RAG application that searches documents and produces a response is necessarily agentic if the route is completely fixed. Conversely, an assistant can include agentic functions for certain operations.
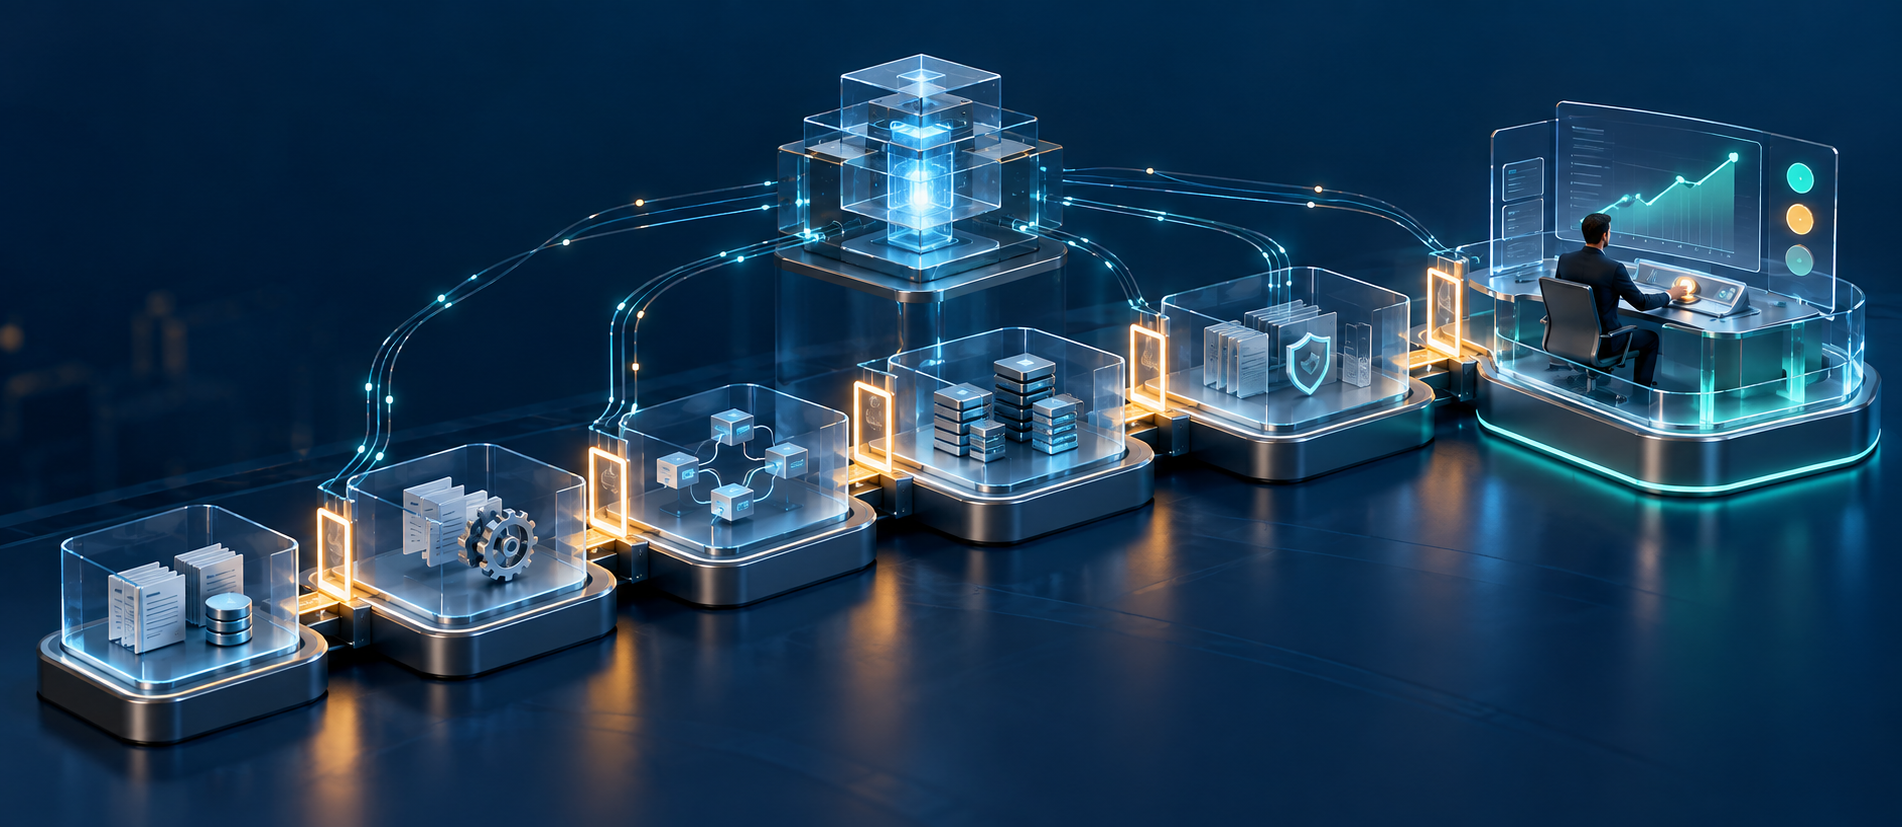
An agent operates, in its simplified form, through a loop:
The loop must have limits: a maximum number of steps, a time and cost budget, tolerance thresholds, and clear stop conditions. Without these limits, autonomy becomes hard to assess and manage.
OpenAI describes three basic components: the model, the tools, and the instructions. For a system used in a company, the full architecture includes several layers.
Before choosing the model, the process must be defined:
A goal like “handle sales” is too broad. “Prepare a first draft offer from requests received by email and send exceptions for approval” can be measured and controlled.
The model interprets the request, analyzes the context, and decides the next step. Its selection impacts quality, speed, cost, the languages, and types of data the system can process.
Not every stage requires the most powerful model. Classifying a request can use a fast and cost-effective model, while analyzing a contract exception may need a more capable one. The right choice is made through evaluations, not through an overall ranking. We’ll detail this decision in the next article in the series.
Instructions define the role, objective, recommended steps, output format, boundaries, and escalation rules. They must be treated like software components: versioned, tested, and reviewed whenever the process changes.
Instructions cannot replace technical controls. A rule written in the prompt, such as “do not send payments without approval,” is useful, but the approval must also be enforced by the orchestrator or the payment system.
These concepts are often confused:
Context is a finite resource. More information does not automatically mean a better result. Irrelevant documents, excessive history, and too many tools can decrease accuracy and increase costs.
Memory should not be enabled by default for every conversation. The company must decide what is kept, for whom, for how long, who can correct the information, and how it is deleted.
Tools connect the agent to the world outside the model. They can provide access to:
A tool may allow data reading, action execution, or coordination of a process step. Separation is important. An agent that needs to check an order doesn’t automatically need the right to cancel it.
Tools can be connected via proprietary APIs, functions, or standard protocols. MCP standardizes access to tools and data sources, but it does not replace authentication, authorization, auditing, or approval rules.
Orchestration controls the agent’s loop: task order, limits, error handling, retries, approvals, and hand-offs to a person or another agent.
The common recommendation in current guides is to start with the simplest architecture that solves the problem. A single agent with well-defined tools is generally easier to test and manage than a network of agents.
A multi-agent system becomes justified when roles are truly distinct, a single agent’s context becomes overloaded, or evaluations show that separation improves results. Complexity, in itself, is not an advantage.
An agent accessing a company’s systems must have an identifiable identity and minimal permissions. Their actions must be attributable during an audit.
Basic controls include:
OpenAI separates automated validations from human approval: guardrails verify inputs, outputs, or tool calls, while human review pauses execution until a person approves or rejects the action.
In a concept paper published as an initial draft, NIST examines identification, authorization, auditing, and non-repudiation of agents as distinct areas of work, given the risks from their access to data, tools, and applications.
An agent is not verified simply by reading the final response. The entire path must be tracked:
Agent evaluations use representative tasks, multiple runs, and criteria that check both the outcome and the system’s final state. In production, logs and tracking execution stages enable investigating errors and comparing versions.
A good project starts from the process, not by choosing an AI product.
The initial questions are:
If the path is fixed and all rules can be spelled out explicitly, classic automation may be the right choice.
We measure time, cost, error rates, exceptions, and volume before implementation. Without this baseline, we can’t prove the agent delivers improvement.
At this stage, we also establish the process owner and define what success means. “Responds more intelligently” is not a metric. “Reduces time to the first draft of the offer, without increasing the correction rate” can be measured.
A suitable pilot case has:
It’s safer to start by preparing an action rather than executing it. The agent can draft the offer before being allowed to send it, or prepare an order before it’s authorized for payment.
Begin with a single agent, clear instructions, and only the essential tools. Define structured outputs, handle errors, and set limits for time, cost, and steps.
Only add more agents, extended memory, or fine-tuning if evaluations show a problem these components would solve.
The evaluation set should include:
Testing for a nice-sounding answer isn’t enough. Check for concrete effects and if the agent knows when not to act.
A prudent order is:
The agent must be able to be stopped or rolled back to a previous version. Changes to the model, instructions, tools, or data can alter behavior, so every version needs to be re-evaluated.
Let’s take the case of a distribution company receiving quote requests by email.
Currently, an employee reads the message, identifies the products and quantities, checks stock and prices, looks up commercial terms, requests clarification, drafts the quote, and sends it for approval.
An agent-assisted flow could work like this:
Without approval, the agent should not:
Indicators may include the time to the first version of the offer, the percentage of corrected documents, the rate of correct escalations, cost per request, and conversion rate, if the volume allows for a meaningful comparison.
This example shows why value doesn't come solely from the model. The agent depends on the catalog, inventory, commercial rules, permissions, approvals, and the quality of the existing process.
In everyday language, any adaptation is often called “training.” Technically, the mechanisms differ, and the wrong choice can increase costs without solving the problem.
Company need | Suitable mechanism | What it doesn’t solve |
|---|---|---|
More consistent answers and behavior | Instructions, examples, and structured outputs | Does not automatically provide current information |
Access to up-to-date procedures, products, or documents | RAG or controlled connection to sources | Does not change the model’s parameters |
Reading or modifying applications | Tools, APIs, or MCP | Does not grant secure permissions on its own |
Case continuity between sessions | Controlled memory | Does not mean the model is retrained |
Stable behavior that repeatedly fails at high volume | Evaluations, then possibly fine-tuning | Does not replace current data or integration |
Fixed and fully predictable process | Classic Automation | Does not need agentic autonomy |
Instructions and examples establish the agent’s behavior, terminology, and boundaries. For information that changes, such as procedures, products, prices, or documentation, a RAG system retrieves relevant sources and adds them to the context without altering the core model. Tools and APIs allow the agent to work with company applications within authorized permissions.
Memory keeps only information selected through an explicit policy, such as the status of a request or certain approved preferences. The agent does not “learn automatically” from every conversation, and stored information must be possible to correct and delete.
Fine-tuning adapts the parameters of a model by continuing training on specific data. It is mainly justified when a stable, repetitive task requires more consistent behavior, there are enough clean examples, and improvement can be measured. It does not replace access to updated data, integration with applications, permissions, or evaluation. We will analyze these options separately in the article dedicated to AI agent specialization.
The market shouldn’t be seen simply as a list of LLM models. A company decides who controls the agent’s loop, where it runs, what data it can see, what actions it can perform, and who operates it.
Implementation model | Startup time | Company control | Integration effort | Suitable for |
|---|---|---|---|---|
Agent integrated into an existing application | Low | Low or medium | Low | Standard tasks in CRM, support, productivity, or commerce |
Managed agent platform | Low or medium | Medium | Medium | Fast launch, infrastructure and observability managed by provider |
Custom agent with SDK or software framework | Medium or high | High | High | In-house processes, special integrations, and control over the execution environment |
Multi-agent system or interoperable integration | High | High | High | Coordinating multiple roles or integrating agents and platforms, after validating a simpler architecture |
In practice, companies can use agent functions built into the apps they already have, managed platforms provided by a vendor, or custom agents integrated into their own infrastructure. The first option gets started faster, while the last gives more control over data, integrations, and execution rules.
SDKs and frameworks from providers like OpenAI, Anthropic, Google, Microsoft, or open-source projects can accelerate implementation. However, they don’t remove the need to design tools, conduct testing, ensure security, or provide maintenance. Protocols like MCP and A2A reduce some of the integration effort, but don’t replace authentication, authorization, auditing, or approval processes.
For the first project at an SME, the right solution is usually the simplest option that solves the process and can be evaluated. A multi-agent architecture only makes sense if tests show that separating roles leads to better results.
Availability and maturity of components vary by region and can change, so choices need to be rechecked before implementation.
Responsibility can’t rest solely with the model provider or the generic 'IT department.' Organizational readiness guides separate platform responsibilities from those of the team owning the process.
Role | Main responsibility |
|---|---|
Business sponsor or owner | Approves purpose, budget, autonomy level, and acceptable risk |
Process owner | Defines procedure, exceptions, indicators, and escalation cases |
Domain specialist | Validates examples, sources, and result accuracy |
Technical owner | Manages integration, versions, execution environment, errors, and rollback to a stable version |
Security and data officer | Approves sources, access, retention, personal data, and user separation |
Human operator or approver | Review sensitive cases and decide whether the action can proceed |
In an SME, the same person may take on multiple roles. However, responsibilities should not be eliminated. We need to know who can modify instructions, who approves an integration, who investigates an incident, and who has the authority to stop the agent.
Ongoing administration includes:
In February 2026, NIST launched the AI Agent Standards Initiative, focused on interoperability, security, identity, and trust. The initiative signals the maturing of the field, but also that important issues are still not being solved consistently.
A plausible scenario for 2027 is that personal agents will more often be tasked with finding offers, booking a service, or preparing a purchase. A company agent could respond in a structured format, checking availability, price, and terms.
The order or payment should remain within the boundaries of a mandate: budget, approved suppliers, timeframe, product type, and approval thresholds. The protocols and initiatives now being developed for identity, interoperability, and payments show the direction, but do not guarantee universal compatibility or adoption by 2027.
For companies, the practical consequence is twofold:
We analyzed the second direction separately in the article “How SaaS Platforms Can Sell to AI Agents”.
Regardless of how technology evolves, the company must retain clear responsibilities for:
When managing agents internally, their autonomy should be treated as delegated authority, while still keeping the people who define, approve, and oversee the system accountable.
Before launching a pilot, we check whether we can answer yes to the following questions:
This checklist is a guide, not a certification standard. The answers show whether we’re ready to build a pilot or if we first need to stabilize the process, data, and responsibilities.
A good project doesn't start with the latest model or with the goal of automating the entire company. It begins with a clearly defined process, an owner, accessible data, and a measurable outcome.
The agent must be observable, correctable, and stoppable. Permissions increase only after evaluations show the system follows the rules and delivers useful results. Sometimes, the right conclusion will be that the process needs classic automation or better organization, not an agent.
In 2027, it will likely become more common to encounter agents in both personal and business activities. For companies, the advantage may not come from granting maximum autonomy, but from having processes, data, and responsibilities structured well enough that useful autonomy can be granted gradually and verified.
We help you choose the right process, model, tools, and control rules, then build a pilot project that can be measured before scaling up.