Last updated: September 26, 2026. This article describes practices and sources available as of this date. The section on 2027 contains planning scenarios, not guaranteed predictions. Legal information is general and does not substitute for case-specific analysis.
An AI agent becomes truly useful when it goes beyond drafting a response and can actually consult applications, modify records, send messages, or kick off processes. That's also when a key question—often postponed in pilot projects—arises: on whose behalf does the agent act, what is it allowed to do, and how can we later prove what happened?
For an SME, the answer shouldn't be a heavy corporate infrastructure. What’s needed is a proportional set of controls, applied where they matter most. The language model can interpret a request and suggest the next step, but it shouldn't be the only component deciding whether that step is authorized. Permissions, approvals, and logging must be enforced by code, identity, and policies outside the model.
This guide explains a practical architecture for AI agents working with email, CRM, documents, invoices, websites, or infrastructure. It doesn’t promise zero risk and doesn’t treat human approval as a universal fix. The goal is more realistic: to limit the impact of an error, stop unauthorized actions before execution, and be able to reconstruct events without turning the log into another sensitive database.
A trustworthy agent needs six properties:
These principles aren’t tied to a specific model or provider. They adapt well-established access control and zero-trust architecture practices to the realities of AI agents: dynamic plans, tool calls, unsafe external content, delegation, and the ability to produce effects across systems.
A chatbot typically generates text that the human reviews before using. An agent, on the other hand, may follow a longer loop:
The risk doesn’t come just from a wrong answer. It may stem from a correctly executed, but inappropriate, action: an email sent to the wrong recipient, a discount given to an ineligible client, a record deleted, a confidential file uploaded to an external service, or a command run in production.
Research confirms that this is not just a theoretical issue. ToolEmu built scenarios for high-stakes tools and identified failures with possible financial or privacy consequences. AgentDojo evaluates agents using tools on unsafe external data and shows how prompt injection attacks can steer agent actions. These results don’t provide a universal risk rate for any implementation, but they do show why even a well-written prompt can’t replace technical controls.
The design rule is simple:
The model proposes. Policy authorizes. The tool executes. The log provides proof.
Authentication answers the question “who is this?”. For an agentic flow, there can be multiple identities involved at once:
If all of these show up in the log under the same generic account, accountability becomes impossible to determine.
Authorization answers the question “what can this identity do to this resource, in this context?”. It’s not enough for the agent to have access to the CRM. Policy must differentiate between reading a contact, modifying it, exporting a list, and deleting the record.
Delegation means that a person or service grants the agent limited authority for a task. Delegated authority should never exceed that of the person and should not be automatically passed to a subagent without explicit limits.
Approval is a one-time decision regarding a specific action. It does not substitute for authorization. An interface asking the user to approve a payment must not allow the payment if the user never had the right to make it in the first place.
Audit is the ability to reconstruct who made the request, what the system decided, what policy was applied, what was executed, and with what result. Audit is not the same as real-time monitoring, nor is it equivalent to storing entire conversations.
The fundamental principles are mature, but identity and delegation for agents are still a developing area. In February 2026, NIST published a conceptual paper on software and AI agent identity and authorization. Its status is conceptual, not a final standard. However, it demonstrates that the industry is trying to apply familiar identity and access management practices to agents, rather than inventing separate security for each platform.
NIST Zero Trust Architecture states a relevant principle: access is decided for every request, with least privilege, and no implicit trust based solely on network position. NIST SP 800-53 Rev. 5 provides established control families for access, least privilege, identification, audit, and log protection. These publications aren’t dedicated recipes just for agents, but form a solid foundation.
In the agent space, OWASP Top 10 for Agentic Applications 2026 and the guide Agentic AI Threats and Mitigations cover risks like objective hijacking, abusive tool use, identity and privileges, tainted memory, and cascading failures. Published on September 1, 2026, the OWASP Agent Control Standard suggests control points and declarative policies enforced during execution, but it’s a new open standard, not automatic proof that an implementation is secure. The current OpenAI documentation on guardrails and approvals recommends placing checks at the boundary of the tool producing the effect. Google Cloud describes dedicated identities, least privilege, deny policies, and human-in-the-loop modes for MCP tools.
The practical takeaway in 2026 is that there isn’t a single product that will automatically turn an agent into a trustworthy system. Control comes from combining identity, policy, isolation, approvals, logging, and testing.
A useful permission for agents must be described along several axes:
Axis | Control question | Example |
|---|---|---|
Tool | What integration can it use? | CRM, email, invoicing |
Operation | What function can it call? | read, create, update, delete |
Resource | On which objects? | only the leads of the Bucharest team |
Fields | Which data can it view or change? | without personal ID numbers and without bank data |
Environment | Where can it operate? | test, not production |
Time | How long is access valid? | 20 minutes for the current execution |
Volume | How many operations can it perform? | maximum 25 messages per run |
Value | Up to what limit? | offer under 5,000 lei, excluding payments |
Destination | To whom can it send data? | only approved domains |
Context | On whose behalf and for what purpose? | for user X, ticket Y |
A generic role such as admin does not express these limits. Nor is a broad scope like crm.write sufficient for an agent who only needs to update the status of a lead.
Avoid shared technical accounts among multiple agents. A distinct identity allows:
The agent’s identity should not obscure the user. In a delegated flow, logs should retain both the agent’s identity and the user or process on whose behalf it acts.
API keys, access tokens, and passwords should not be placed in prompts, memory, or documents consulted by the model. A gateway, a vault, or even a simple internal service can attach the credential only after the policy has approved the request.
Technical preferences are:
RFC 9700 brings together current OAuth 2.0 security practices, and RFC 9396 allows for more detailed authorization descriptions than a simple scope list. Not every SMB needs to implement these protocols themselves, but the chosen provider should be able to explain token audience, expiration, revocation, and privilege limitation.
The phrase “do not delete anything without approval” in the prompt is useful as guidance, but it is not a security barrier. A prompt injection attack, a planning error, or ambiguous context may cause the model to ignore or misinterpret it.
The check must be repeated right before the operation:
This double check prevents situations where the orchestrator accepts an action but the API executes it using an unlimited technical account.
An agent that analyzes invoices doesn’t need the implicit right to pay them. An agent drafting an article shouldn’t be able to publish it automatically. Separation can be accomplished with different tools, different identities, or distinct workflow steps.
For sensitive tasks, a two-step model is useful:
The model does not get direct access to the database if a narrow function such as update_order_status(id, allowed_status), is sufficient.
Not every call requires human intervention. If a person has to confirm every read, the system slows down and people learn to hit “Approve” without checking. This leads to approval fatigue.
A practical classification can start from five questions:
Level | Examples | Recommended control |
|---|---|---|
Low | searching in non-sensitive internal documents, reading product catalog | automatic execution, volume limits, logging |
Moderate | creating drafts, updating a reversible field, internal reply | automatic policy, schema validation, human sampling |
High | external sending, publishing, price modification, access to personal data | explicit approval before effect, current authentication |
Critical | payment, mass deletion, privileged production access, changing bank account | dual control, additional authentication, strict limits or prohibition |
This is a starting matrix, not a legal classification. Thresholds need to be adjusted to the company, process, and real-world consequences.
A proper approval doesn’t require confirmation of a vague intent such as “the agent wants to continue.” The interface must display:
The approval must be cryptographically linked or uniquely identified to the specific action. If the agent changes the recipient, amount, or attachment after approval, the previous approval is invalidated.
The four-eyes principle is suitable for high-impact actions: payments above threshold, changing a supplier’s account, massive data exports, privileged changes in production, or irreversible deletions. The second person must have an appropriate role and must not be the same identity that initiated the request.
An approval request must expire. If the policy or approval service is unavailable, sensitive actions should fail safely, not be executed by default. Denials must be communicated to the agent as a clear final state to prevent repeated re-tries of the same action until control is bypassed.
A useful log answers questions, not just stores text. For each important run and call, it is recommended to have:
For distributed flows, OpenTelemetry provides tracing conventions that can link the agent’s invocation, model calls, and tool executions. These technical traces must be supplemented with policy decisions and business approvals. A simple performance trace is not automatically an audit log.
Auditability does not require retention of the full internal reasoning. This may be unavailable, unstable, or contain data we do not wish to keep. It is more useful to store:
This way, we can explain the observable process without treating a model-generated text as legal justification or absolute truth.
A log that retains tokens, passwords, full prompts, attachments, or personal data without limitation may create a greater risk than the one it aims to reduce. EDPB guidance on the privacy risks of LLMs recommends access controls and logging, as well as minimizing data in logs.
Minimum practices:
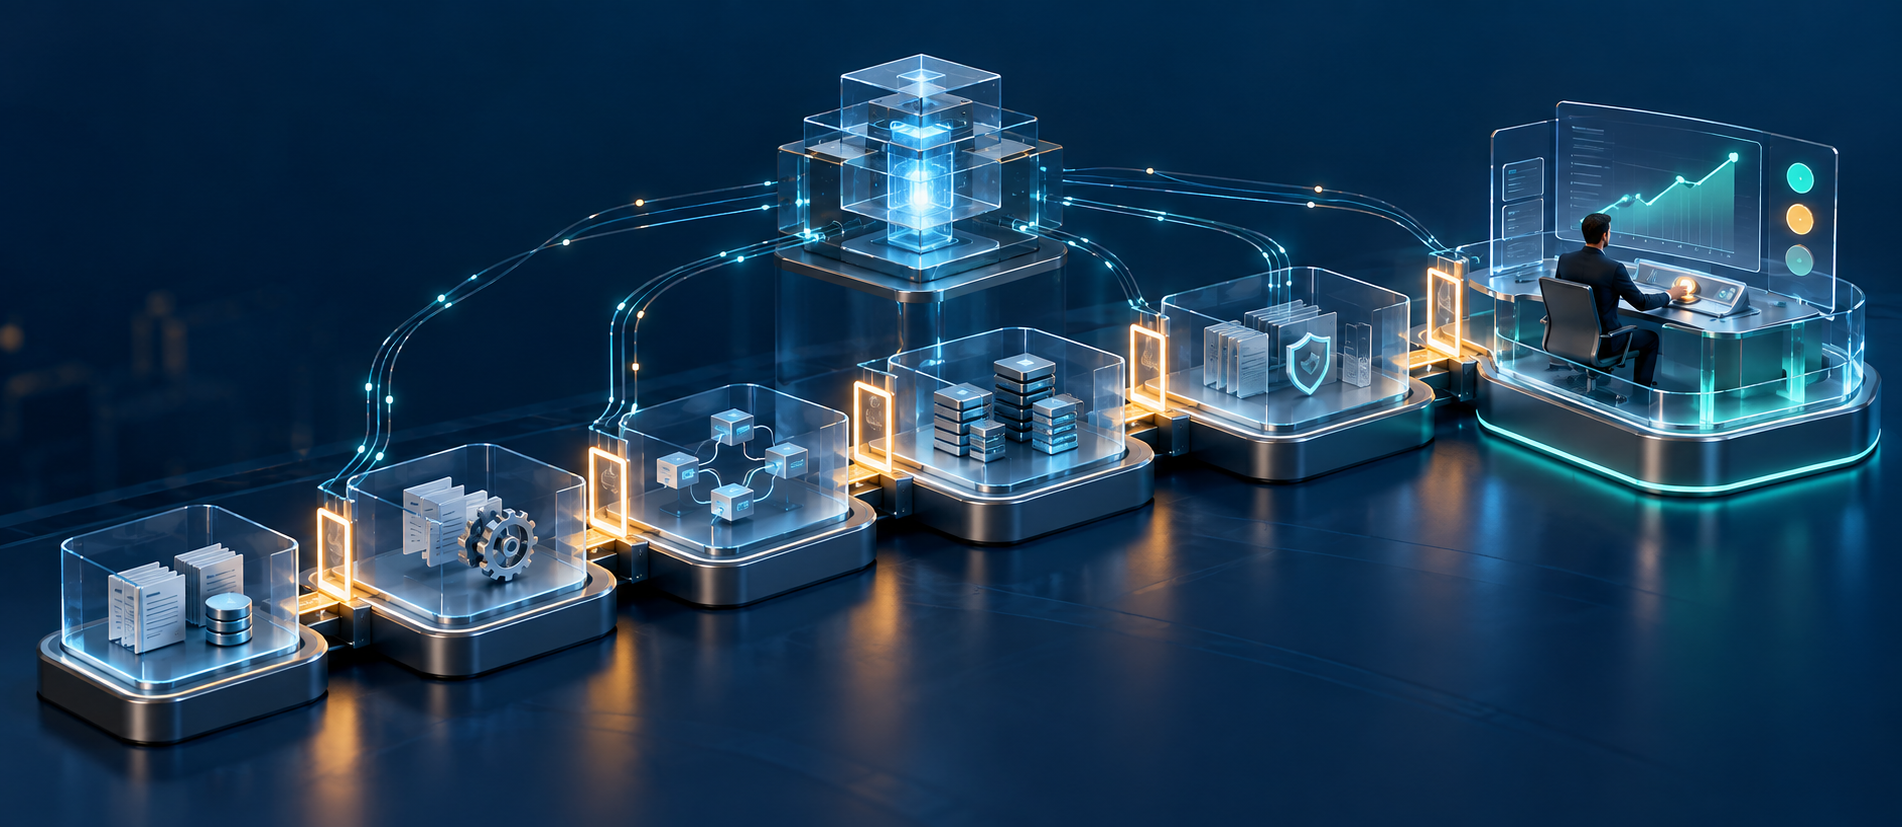
It is not necessary for each element to be a separate product. What matters is separation of responsibilities:
The policy must be enforced in a component that the model cannot alter. If the agent can edit the file that defines its boundaries, control is only superficial.
The following rule is conceptual—not syntax for any specific product:
The advantage of explicit policies is that they can be reviewed, tested, and versioned. Natural instructions in the prompt remain useful for behavior, but deterministic policy enforces authority.
The agent reads a client request, consults the catalog, and prepares an offer. A balanced setup might automatically allow:
Approval would be required for:
It would completely refuse exporting the client database and changing bank information. The log would link the sent offer to the prices and discount policy in effect at that moment.
The agent can extract invoice data, verify the supplier, and prepare the payment. However, the right to read invoices does not imply the right to make payments.
A secure flow separates:
Changing the IBAN and the first payment to a beneficiary should trigger an additional check, not be learned automatically from a received email.
The agent researches and drafts an article in the CMS. Reading existing articles and saving a draft are reversible operations. Publishing, modifying an already published article, and deleting an image have external impact.
Permissions can be separated as follows:
This model prevents both accidental publishing and the loss of changes made in the meantime by another person.
The Model Context Protocol standardizes how applications expose tools and resources to agents. The protocol does not remove the obligation to design permissions. An MCP server that exposes a dangerous function with an overly broad token remains dangerous.
Current MCP documentation and SDKs are based on OAuth and protected resource metadata. Relevant practices include:
The MCP specification and guides must be checked at implementation time, as the protocol evolves. For an SME, the essential criterion is not just MCP compatibility, but the provider's ability to limit each tool and generate useful audit trails.
An agent should not be promoted to production just because it successfully completes a few demos. Testing must cover both success and refusal.
Explicitly check:
Insert into documents, emails, and test pages instructions that try to persuade the agent to ignore its objective, disclose data, or use another tool. The goal isn't just to check if the model says no. The crucial test is whether the authorization system blocks the effect even if the model suggests a wrongful action.
Run these tests after any change to the model, prompt, tools, policies, or connectors. An old evaluation doesn't guarantee the behavior of a new setup.
Before going live, the agent can work in shadow mode: it proposes actions, and the system compares them to human decisions without any real impact. The next step allows low-risk operations to run automatically while requiring approval for others. Autonomy increases only based on observed data, not just because the demo “seems smart.”
Besides time saved and completion rate, track:
A very high approval rate doesn't necessarily mean safety. It might signal unnecessary approvals or reviewer fatigue. A very high denial rate might point to a poorly configured agent or a policy that doesn't fit the process.
Permissions and auditing are technical controls. They alone don't determine the legality of processing or classify an AI system.
If the agent processes personal data, GDPR principles still apply: defined purpose, data minimization, security, retention periods, and the operator’s ability to demonstrate compliance. The audit log must be designed in line with these principles. Keeping everything “for audit” indefinitely and without clear purpose isn’t a prudent solution.
European Union Artificial Intelligence Act includes requirements for automatic log retention and human oversight for some high-risk systems. These obligations do not make every internal agent a high-risk system. Classification depends on usage, the organization’s role, and context. In addition, the timeline for applying some rules to high-risk systems was modified and clarified in 2026. The European Commission maintains an updated page about AI Act application.
For decisions affecting employees, lending, access to essential services, or other rights, a specific legal assessment is required. This article provides a technical framework, not legal advice.
The prompt doesn't reduce the account’s privileges. If the agent is compromised or makes a mistake, the full administrator impact still applies.
Initial consent for integration isn’t approval for all future actions. Sensitive operations must be assessed in context.
Too many approvals create routine. Furthermore, a person may be misled by an incomplete description. The interface must show the exact effect, and policy must block unauthorized actions regardless of superficial approval.
Logs from a single vendor may show the model call, but not the end-to-end flow from user, orchestrator, policy, approval, to the final API. Check for correlation identifiers and export capabilities.
This can copy personal information, secrets, and entire documents into the log. Define required fields, mask content, and store references or hashes where full text isn’t justified.
Chain delegation can amplify privileges and break the link to the original user. Each sub-agent should be given a set of rights no greater than, and usually more restricted than, the previous agent, tailored to its subtask.
Retrying without an idempotency key and without checking state can result in duplicate payments, orders, or messages. Tools with side effects must distinguish a safe replay from a new operation.
The following are plausible scenarios, not certainties.
NIST initiatives and evolving cloud platforms point to the possibility of dedicated workload identities for agents, with better delegation and traceability. We are likely to see tighter integration between agent registries, IAM, gateways, and policy systems.
Instead of static, broad scopes, platforms may increasingly use on-demand authorization, restricted by action, resource, amount, and time window. This would reduce permanent credentials but might increase complexity and reliance on central services.
Moderate-risk operations could be automatically evaluated by a policy engine plus an independent control model. However, 2026 research shows that model-based monitors can themselves be bypassed. Therefore, such an evaluator should not replace deterministic barriers for critical operations.
As tasks move between agents and organizations, portable evidence of delegation, policies, and outcomes will be required. Observability conventions help, but a universal solution for non-repudiation and full provenance in agentic flows does not yet exist.
For an SME, the sound strategy is to use existing standards now, avoid lock-in with proprietary formats, and retain control over identities, policies, and essential logs.
Trust in an AI agent should not be measured by how convincingly it explains what it plans to do. It must be built through verifiable limits.
A trustworthy agent is not one to which we grant unlimited access simply because the model appears capable. It is an agent that can operate efficiently within a clear perimeter, uses temporary authority, requests appropriate approval before any effect, and leaves sufficient evidence for verification. If an error or attack occurs, the architecture limits the damage and allows intervention.
For most SMEs, the first step is not acquiring a complex platform. It is inventorying actions, separating reading from writing, removing administrative accounts from automated flows, and defining three categories: what the agent can do alone, what requires approval, and what it is never allowed to do.
Would you like us to assess a specific process, the necessary permissions, and the control architecture best suited to your company? We can turn a promising pilot into a measurable, auditable, and production-ready system.