A language model may know a lot about the world, but it doesn’t automatically know the latest version of your internal procedure, what was decided in a meeting, which clause applies to a client, or which incident affected a particular server. Even a very capable model works only with the knowledge it was trained on and whatever data is provided in the current conversation.
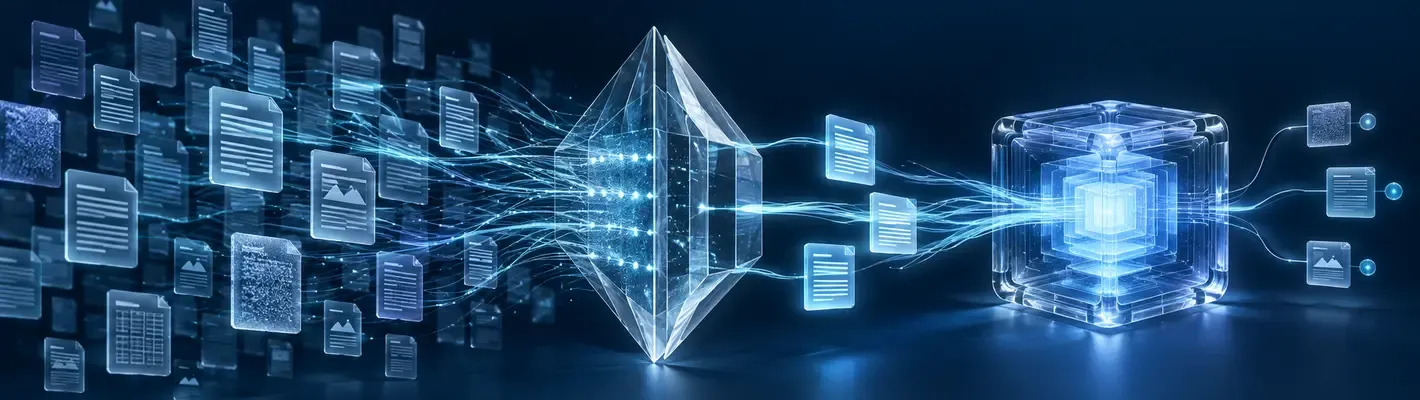
RAG, short for retrieval-augmented generation, is one of the ways an AI application can search for relevant information before generating an answer. Instead of asking the model to respond only from its general knowledge, we supply it with selected excerpts from documents, databases, or other approved sources.
The idea sounds simple: search, add the results to context, then generate the answer. In practice, the difference between a convincing demo and a genuinely useful system comes down to the quality of the documents, how they’re extracted and broken up, the search method, how permissions and updates are handled, as well as the quality of citations and evaluation.
As of September 24, 2026, there’s no single RAG method that’s best for every organization. However, there’s a set of practices that are mature enough for production, and several advanced approaches worth using only when the problem warrants it.
RAG didn’t arise from a single breakthrough. Earlier systems like DrQA combined search with reading comprehension, while kNN-LM and REALM they were exploring the use of external memory. The paper published in 2020 by Patrick Lewis and his collaborators introduced the term RAG and a family of generative models that combined a sequence-to-sequence model with a dense index built from a version of the Wikipedia encyclopedia.
The distinction remains useful:
RAG is, therefore, an architecture, not a product or a database. An implementation can use a classic search engine, a vector database, PostgreSQL, a knowledge graph, managed cloud services, or any combination of these.
The goal is not to load all the company’s information into the prompt. The goal is to find a small set of relevant, authoritative, and up-to-date evidence for the given request.
RAG is often confused with agent memory, the context window, or fine-tuning. These mechanisms solve different problems.
Concept | Where the information resides | Main role |
|---|---|---|
Model knowledge | Within the parameters resulting from training | General knowledge and learned patterns, difficult to update and assign to verifiable sources |
Context window | In the current query sent to the model | Temporary workspace for instructions, messages, and evidence |
Conversation history | In messages and results saved by the application | Continuity between replies and sometimes between sessions |
Agent memory | In persistent records about preferences, decisions, or events | Long-term personalization and continuity |
RAG | In external documents, indexes, and knowledge bases | Brings relevant, updatable, and citable information into context |
Fine-tuning | In the modified parameters of the model | Adjusts behavior, style, or performance for a specific task |
Agent tools | In APIs, databases, and external applications | Read current state or perform actions |
RAG does not mean the model was “trained on the company’s documents.” The documents remain outside the model and are accessed at query time.
RAG does not guarantee the answer is true. If the system finds an old, incorrect, or compromised document, the answer may accurately reflect that source and still be wrong. That’s why groundedness, meaning support for the answer by the retrieved context, is not the same as truth.
RAG does not replace an API or an SQL query. For current inventory, the amount of an invoice, or the status of an order, the right source is often the operational system. A document index can explain the applicable policy but shouldn’t make up the state of a transaction.
Procedures, decisions, manuals, and lessons learned can become searchable in natural language. The answer should indicate the document, version, and date, and users should only see the information they have access to.
Documentation, policies, and guides can be accessed via RAG. Customer, subscription, and ticket data are read via API. Changes, refunds, and external communications remain separate actions, with authorization.
The agent can find relevant services, case studies, and technical answers, then prepare a first draft of an offer. Current prices and terms must be pulled from the valid commercial source, not from an old document returned by semantic search.
A system can identify clauses, compare versions, and point out applicable policies. The final legal decision should not be delegated to the model, and sources must remain verifiable.
Code, documentation, tickets, incidents, and runbooks can be searched together. Lexical search remains important for errors and identifiers, while semantic retrieval helps when the same issue is described differently.
Course materials, manuals, bibliographies, and activities can be queried with page citations. For tables, maps, diagrams, and scanned pages, a multimodal strategy or good structural extraction is needed.
RAG can explain products and policies, find alternatives or documentation, and assist with comparisons. Price, availability, compatibility, and current business terms must be checked in the catalog and operational systems.
An agent can search reports, internal documents and public sources, group the evidence, and generate a report with citations. For major conclusions, human verification of sources and claims is required.
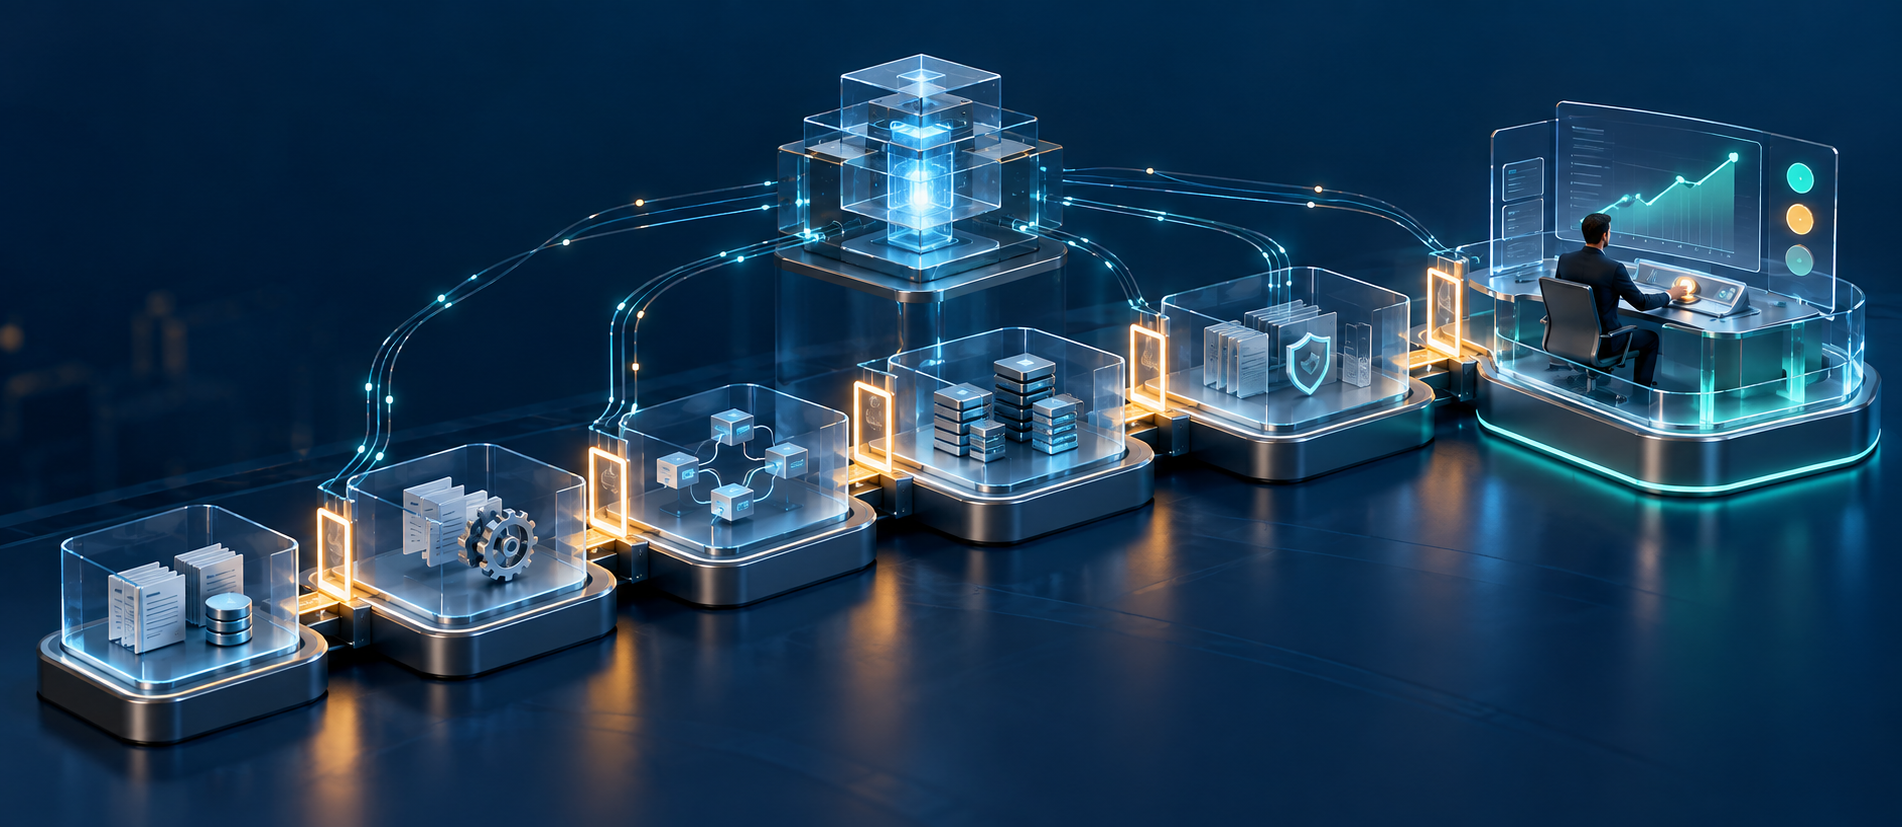
A complete system has two flows: knowledge preparation and question answering.
Sources can include PDFs, Office documents, web pages, emails, meeting notes, wikis, support tickets, contracts, manuals, files from Nextcloud, SharePoint, or Google Drive, and, where appropriate, data from CRM, ERP, or relational databases.
A list of files uploaded once is not yet a knowledge base. The system must know the original source, who owns it, what version is current, and when it should be synchronized or removed.
Text must be extracted without losing the structure that gives it meaning. In a real document, headings, sections, footnotes, columns, tables, images, and the connections between pages can change how information is interpreted.
For a scanned PDF, OCR is generally required, or a multimodal pipeline that processes page images directly. For a manual or a complex report, it may be necessary to analyze the page’s visual structure, extract tables separately, and retain page coordinates. In many projects, the quality of this stage can impact results more than changing the language model.
Documents are split into fragments, often called chunks. Fixed size and overlap between fragments are a starting point, not a universal rule.
For a company’s documents, it’s more useful to preserve:
Azure documentation describes both semantic chunking, and general chunking strategies for vector search. There’s no optimal size that can be copied from a provider and applied to any corpus.
Each fragment must be evaluable based on its own metadata or a reliable reference to the document’s metadata, so that filtering and audit use:
Permissions are enforced before the text is passed to the model. A prompt instructing the model not to disclose another client’s documents is not an access control. The search engine must exclude from the results any fragments, documents, or sources the user is not authorized to see.
Fragments can be indexed in several ways:
In a conversation, a question like "but what about the contracts from 2025?" cannot be searched correctly without the context of the previous message. The application can rephrase the request into a standalone query, identify the language, entities, time range, and likely source.
Complex questions can be split into sub-questions. This stage helps with research and multi-hop scenarios but adds latency, cost, and the risk of the system drifting from the user's intent.
The system retrieves a set of candidates, can combine results from several methods, and can use a re-ranking model to select the passages that best answer the question.
The first stage aims not to miss important evidence. Re-ranking aims to remove noise before the information reaches the model's context.
The model receives the question, instructions, and selected passages. The application may ask it to answer using only evidence, to indicate sources, and to state explicitly when information is insufficient.
In a verifiable implementation, citations should lead to the most precise location permitted by the platform: fragment, page, or at least the document used—not just the homepage of a website. For internal documents, version, date, page, and source status are useful.
An observable system should preserve the technical trace of the question: generated queries, filters applied, documents retrieved, scores, answer, citations, cost, and latency. Sensitive data must be masked before logging or kept according to a clear policy—not recorded in full by default.
The expression second brain is useful as a metaphor for a personal or organizational knowledge base, but does not designate a standard technology.
A truly useful "second brain" is not just a chatbot where all files have been uploaded. It's an administered system, consisting of:
For example, "the user prefers concise reports" is suitable information for an agent's personal memory. "Backup procedure, version 4.2" is documentary information that should be retrieved from the official source. "Free server space now" must be read via a monitoring tool.
RAG can serve as the retrieval engine of such a system second brain, but it does not make up the whole system. Without permissions, versioning, and update rules, it may turn document chaos into a compelling answer—but not into a trustworthy knowledge source.
Products such as NotebookLM exemplify a notebook based on the user's chosen sources. For self-managed implementations, there are projects such as AnythingLLM, Khoj or RAGFlow. These can speed up prototyping, but choosing a product doesn't automatically solve document quality, permissions, or evaluation issues.
Methods like BM25 prioritize terms that appear in both the query and the document. They are particularly useful for:
Lexical search shouldn’t be dismissed as outdated technology. The comparative study BEIR showed that BM25 remains a robust benchmark across diverse domains.
A semantic vectorization model (embedding model) transforms the query and passages into numeric representations. The engine searches for nearby vectors, allowing an idea to be found even if the query uses different words than the document.
Dense Passage Retrieval was a key piece of work in this area. Dense search is great for paraphrasing and semantic similarity but may miss exact identifiers and can return thematically similar fragments without the needed answer.
Hybrid search combines lexical and vector search and then merges the result lists. A common method is Reciprocal Rank Fusion, which combines document positions without assuming the two systems’ scores are directly comparable.
For many production projects, hybrid search is a safer starting point than relying solely on vectors. The documentation for Azure AI Search, Qdrant, Weaviate and OpenSearch describe implementations of this model.
Models like ColBERT retain token-level representations and compare the query and passage more granularly. Compared to methods that use a single vector per fragment, this family can improve accuracy but requires more storage and evaluating a higher number of representations. ColBERTv2 significantly reduced the storage required compared to the method's first generation.
The same principle of multiple representations can be used for different fields, different languages, or combinations of text and images.
Contextual Retrieval, described by Anthropic in 2024, adds a short explanation derived from the full document to each fragment before indexing. For example, a passage mentioning “the company’s revenue increased by 3%” can retain information about the company, time period, and report.
In their own evaluation, Anthropic reported that contextual embeddings together with contextual BM25 they relatively reduced the retrieval failure rate in the top 20 fragments from 5.7% to 2.9%. After reranking 150 candidates and keeping the top 20, the rate dropped to 1.9%, a relative reduction of 67%. The results come from the provider's evaluation and do not guarantee the same outcome on any corpus.
More advanced systems can:
HyDE is a dense retrieval method zero-shot, requiring no relevance labels. It generates a hypothetical document, then uses only its representation to retrieve real, similar documents. The hypothetical text may contain false details and should not be used as evidence. Multiple queries and question decomposition can improve coverage, but may also increase cost and introduce off-topic results.
These techniques are triggered after evaluation. Not every question needs five reformulations and several search rounds.
An agent should not send every request to the same vector database. It can select the appropriate tool for the type of information requested.
Tool | Best suited for | Example |
|---|---|---|
Lexical search | Identifiers and exact phrasing | Finding an error code in a runbook |
Vector search | Concepts and paraphrases | Finding a procedure described in different terms |
Hybrid search and reranking | Mixed corpora and real-world questions | Technical documentation, policies, and support |
SQL or operational API | Exact values and current state | Stock, invoices, orders, or metrics |
Knowledge graph | Relationships and multi-step questions | Links between incidents, vendors, and components |
Web search | Recent public information | Rules, documentation, and market information |
Document management system or object storage | Documents and their original permissions | Nextcloud, SharePoint, Drive, or S3 |
Multimodal tool | Scanned pages, tables, and diagrams | Manuals, invoices, and complex reports |
Persistent memory | Selected preferences and decisions | Preferred report format |
Action tool | Modifying a system | Creating a ticket or updating a CRM |
When the agent searches for the return policy in a manual, they use retrieval. When they check an order’s status, they use the store’s API. When they initiate a refund, they’re executing an action that requires permissions, limits, and, depending on risk, human approval.
Model Context Protocol can expose sources and tools in a common format. However, MCP is not a RAG engine. It can provide the agent with a tool— search, a fetch, a database query, or a business action, and the application decides how these are used.
Increasingly large context windows do not automatically eliminate retrieval. Introducing a small number of full documents may be the simplest solution when the information can be included in context at a reasonable cost and the relationships between sections are important.
For large, frequently updated collections or with differing permissions, RAG maintains clear advantages: it selects information, reduces the amount sent to the model, allows filtering, and can link the answer to the source.
The study Lost in the Middle showed, for the evaluated tasks and models, that performance often decreases when relevant information is located in the middle of a long context. This result should not be generalized to all current models by default. LaRA, published at ICML 2025, found that the choice between long context and RAG depends on model capability, context length, task type, and retrieval quality, which justifies evaluation and routing between the two approaches.
The pragmatic approach is to measure three variants: direct context, RAG, and a hybrid solution that routes the question to the suitable method.
An agentic system can decide if retrieval is needed, select the source, decompose the question, perform searches in parallel, evaluate the relevance of results, and repeat the search.
This flexibility is useful for research and questions that require multiple steps. However, it adds steps, latency, cost, and new points where errors can occur. The system must have limits on the number of steps, allowed sources, budget, and time.
According to the documentation Azure AI Search for agentic retrieval, the extractive component is generally available via the stable API 2026-04-01, while planning with LLM, synthesis, and some features for multi-turn conversations still use 2026-08-01-preview. This separation is a good example of the uneven maturity of components.
Self-RAG trains the model to decide when to search and uses reflection tokens to evaluate evidence and its own generation. Corrective RAG uses a results evaluator and can trigger corrective steps, including web search. Adaptive-RAG uses a complexity classifier to choose between no retrieval, a single step, and iterative retrieval. These are important directions, but the implementations in papers should not be confused with a universal option that can just be enabled in a product.
Classic RAG finds fragments close to the question. However, some queries require a perspective on the entire corpus: recurring themes, relationships between organizations and events, or connections among incidents, components, and suppliers.
GraphRAG, developed by Microsoft Research, extracts entities and relationships, builds communities, and generates summaries for them. The original paper focuses especially on global questions about themes and patterns across the whole corpus. Microsoft’s implementation also documents local search methods separately. RAPTOR builds a hierarchy of fragments and recursive summaries.
These methods may be suitable for investigations and cross-sectional analyses, especially in corpora where relationships are essential. Building and updating the structure adds cost and complexity. GraphRAG isn’t an automatic recommendation for a FAQ, catalog, or finding an exact clause.
Real-world documents contain more than just text: tables, charts, boards, images, formulas, and complex visual structures. A mature approach combines OCR, structure parsing, and descriptions of visual elements, maintaining the link to the original page.
A new direction is to directly index page images. ColPali is a page-level visual retrieval model based on multiple representations. VisRAG is a fully visual indexing, retrieval, and generation pipeline, without first converting all content to text. Both works were published at ICLR 2025.
Commercial services have started to include multimodal parsing and retrieval. Amazon Bedrock Knowledge Bases documents multimodal flows for text, images, audio, and video, while Gemini API File Search announced in 2026 multimodal processing and page-level citations.
For a company, the prudent approach is to retain text, structure, and the page, and then add visual retrieval where tables and images change the answer.
“Local” and “cloud” do not automatically determine security or quality level. They describe the distribution of control and responsibility.
Implementation model | Advantages | Responsibilities and trade-offs |
|---|---|---|
On-premises (own infrastructure) | Direct control over documents, indexes, and logs; ability to use local models | The team manages authentication, updates, backup, monitoring, scaling, and the security of the entire technical stack |
Self-managed in private cloud | Architectural control and good integration with the existing infrastructure | Requires operational expertise and a clear model for cost and availability |
Externally managed service | Faster pilot implementation and scaling; less reliance on own infrastructure | Data retention, usage, region, export, deletion, costs, and vendor dependency must be checked |
Hybrid | Documents and permissions can stay in own infrastructure, and only required fragments are sent to the external model | More complex architecture; must track which data crosses each trust boundary |
A local vector engine doesn’t necessarily require a GPU. Resources depend on index volume, desired latency, and the models used for vectorization and reranking. Local generation with a large model is a separate issue from vector storage and search.
Products should be compared within the same category:
Layer | Role | Examples |
|---|---|---|
Search and storage engine | Lexical and vector index, filters and ranking | pgvector, Qdrant, Weaviate, Milvus, Vespa, OpenSearch, Elasticsearch |
Managed RAG service | Ingestion, indexing, and retrieval managed by provider | OpenAI File Search, Azure AI Search, Bedrock Knowledge Bases, Google Agent Search and RAG Engine |
Vectorization and reranking models | Semantic representation and candidate reranking | OpenAI, Cohere, Voyage, Jina and open-source models |
Orchestration framework | Connectors, workflows, retrieval mechanisms, agents, and evaluation | LlamaIndex, LangChain and LangGraph, Haystack |
Interface or complete application | Experience for documents, chat, and agents | AnythingLLM, RAGFlow, Open WebUI, Dify, Khoj |
Generative model | Answer formulation based on context | Local models or services from external providers |
PostgreSQL with pgvector is a pragmatic choice when the company already uses PostgreSQL and the corpus is moderate in size. Data, metadata, permissions, and vectors can remain in the same database. Ingestion, hybrid search result merging, and reranking must be assembled around the extension, in SQL and/or in the application.
Qdrant is a dedicated engine for dense, sparse, and multi-representational vectors, with filters and hybrid queries. It can run locally or as a managed service and is suitable when retrieval becomes a separate component of the architecture.
Weaviate combines vector search, BM25F and hybrid search, offering options for multi-tenancy and integration modules. It's more integrated, but requires careful collection and resource management.
Milvus offers Lite, Standalone, and Distributed editions, plus the Zilliz Cloud service. The distributed version is typically justified by high volumes or requirements for availability and scaling, not as the default choice for an SME's first project.
OpenSearch and Elasticsearch are natural choices when the organization already uses these ecosystems for search and analytics. Both combine lexical search with vector functions, but cluster operation and relevance tuning require experience.
Vespa is suitable when multi-stage ranking and business signals are key product features. Its flexibility comes with a steeper learning curve.
OpenAI File Search is a hosted tool for the Responses API, built on top of Vector Stores. It handles files, chunking, indexing, semantic and lexical search, file attribute filters, and file-level citations. It's a fast track to a pilot when your app already runs on the OpenAI ecosystem, with less control over the internal logic than in a self-hosted architecture.
Azure AI Search offers full-text, vector, and hybrid search, semantic ranker, OCR, and built-in vectorization. It's especially relevant in the Azure and Microsoft Entra ecosystem. Direct integration with SharePoint and access control list propagation must be checked independently, as some capabilities are still in preview. The same goes for agentic features not yet generally available.
Amazon Bedrock Knowledge Bases offers Managed Knowledge Base, where the service administers ingestion, indexing, storage and retrieval, as well as Customer-managed Knowledge Base, where the client controls ingestion flow and the vector store. Some features, including certain third-party connectors and access control list filtering, are only available in the managed option. The RetrieveAndGenerate flow can produce responses with citations, while Retrieve returns retrieved results. Model and feature availability depends on the region.
Agent Search on Gemini Enterprise Agent Platform, the current name for the product formerly known as Vertex AI Search, is oriented towards searching websites and documents. RAG Engine on Gemini Enterprise Agent Platform is intended for custom applications and agents. Some modes and features still have preview or region-specific limitations.
Pinecone is a managed engine for semantic and hybrid search with hosted filters, namespaces, embeddings, and reranking. It reduces operational workload but doesn't replace ingestion, authorization, or application evaluation.
Cohere offers models and APIs for semantic vectorization, reranking, and document parsing, but is not primarily a vector database. A Cohere rerank model can be used on top of results from pgvector, Qdrant, OpenSearch, or other engines.
LlamaIndex offers connectors, ingestion, indexes, retrieval mechanisms, query engines, pipelines, and agents. The LlamaParse platform adds hosted services for parsing and document processing.
LangChain and LangGraph provide components and control for custom applications, including agents that decide when and where to search. The large number of integrations helps, but may result in an architecture that's hard to follow if clear boundaries aren't maintained.
Haystack builds modular pipelines from components, document stores, retrieval and reranking mechanisms, agents, and tools. It's good when your team wants explicit control over each step and the ability to change providers.
A software framework speeds up implementation. It doesn't decide for the team which documents are authoritative, what permissions apply, or what level of quality is acceptable.
A RAG system brings company documents into an operational pipeline where a model interprets natural language. This integration should be treated as a new security boundary.
A document, email, or website may contain malicious instructions directed at the model. OWASP describes an indirect prompt injection as a situation where the model receives external content that can alter its behavior.
Useful measures include:
Delimiters and system prompts reduce the risk but are not, on their own, a security control.
Authorization must be applied at retrieval time, on the fragment, document, or authorized source level. Caches have to be isolated or indexed according to the full relevant authorization context, including tenant, user, groups, roles, and access control list version. The system should be subject to deliberate cross-access testing.
The deletion of the original document must be propagated to fragments, vector representations, secondary indexes, caches, and pre-generated results, as per the retention policy. Each source requires a stable identifier, version, effective date, and status.
Vector representations should not be treated as a guaranteed form of anonymization. The research Text Embeddings Reveal (Almost) As Much As Text demonstrates why simply converting text into a vector does not automatically eliminate the risk of exposure. Only necessary data is indexed, and personal information and secrets are eliminated or pseudonymized where the purpose allows.
In contracts with external vendors, retention, use of data for training, processing region, deletion, export, and subcontractors must be checked. “Data is not used for training” does not automatically mean “zero retention.”
A hybrid architecture can keep documents, access control lists, and retrieval within the internal infrastructure, sending the external model only the strictly necessary fragments, and masking them where possible.
OWASP RAG Security Cheat Sheet offers a practical checklist for ingestion, embeddings, access, provenance, caching, monitoring, and deletion. The dedicated article on prompt injection will detail these risks separately.
A demonstration is not an evaluation. For a pilot, a set of real questions, expected sources, and clear conditions for situations where information is missing are required.
Evaluation is separated into levels:
Level | Question evaluated | Sample metrics |
|---|---|---|
Retrieval | Does it find the required information? | Recall@k, Hit Rate@k |
Ranking | Does it place useful evidence before noise? | Precision@k, MRR, nDCG@k |
Generation | Does it answer correctly and sufficiently completely? | relevance, correctness, completeness |
Faithfulness | Are statements supported by the context? | faithfulness, groundedness, claim verification |
Citations | Do sources support and cover key assertions? | citation correctness, citation completeness |
Abstention | Does it refuse to make things up when evidence is missing? | correct refusal rate and unjustified response rate |
Operations | Is it sustainable in production? | p50 and p95 latency, cost, tokens, error rate |
Security | Does it respect access and withstand hostile content? | isolation tests between organizations, resistance to prompt injection, and deletion propagation |
Ragas and ARES offers methods for assessing context relevance, faithfulness, and answer quality. RAGChecker breaks down answers into statements and tries to separately diagnose retrieval and generation.
Definitions for faithfulness, groundedness and citation accuracy vary across evaluation frameworks. Scores are not directly comparable unless we use the same rubric, test set, and evaluator type.
Evaluators based on other models are useful for quick comparison, but must be calibrated with examples reviewed by humans. An automated score does not replace review of critical cases.
An SME test set should include:
For each case we keep the question, role, expected sources, mandatory statements, acceptable abstention behavior, and error severity.
RAG is not a mandatory stage for every AI application.
It may be unnecessary or disproportionate when:
Sometimes, the first useful project is not a RAG chatbot, but document ordering, deduplication, establishing the official version, and introducing access rights.
A good first pilot answers a clear set of questions from a well-defined corpus. For example: approved internal procedures, documentation for a family of products, or service runbooks.
Identify the owner, version, and update frequency. Documents without authority or known status are not automatically included in the index.
Start with structural parsing, metadata, lexical and vector search, filters, result re-ranking, and citations. Don't introduce GraphRAG or agent loops until you identify, through measurement, a baseline limit.
Collect real questions, expected answers, and no-answer cases. Measure retrieval separately from final answer formulation.
We check isolation of roles and tenants, expired documents, deletion, prompt injection, conflicting sources, and refusal to fabricate answers.
We evaluate at least one local or self-managed setup and one managed service, using the same documents and questions. The decision is based on quality, total cost, latency, control, operations, and risk—not on the number of features listed in a presentation.
Early users can see sources, mark incorrect answers, and have a clear path for escalation. We expand the corpus and autonomy only after measurements show the system remains useful and controllable.
The first step isn’t choosing a vector database, but defining a real problem and the sources that can solve it. We can work together to analyze which data is worth connecting, which search method fits, and whether the solution should run on your own infrastructure, through cloud services, or in a hybrid setup. Then, we can define a measurable pilot project with controlled access and clear quality criteria.