Shared memory for AI agents: what to keep, who can read it, and when to forget
Series II: From infrastructure to agentic projects in production. Episode 10 of 20.
In a project with several AI agents, the next agent needs to find relevant decisions without receiving the entire conversation history. But a claim repeated three times is still a claim; it does not automatically become an approved decision. For the fictional B2B request and document portal in this series, the useful question is: what information deserves to survive across tasks, and who confirms that it is still valid?
Four different things often called “memory”
Conversation context is the text available to an agent during the current session. It helps continue a discussion but may contain abandoned ideas and conflicting instructions. Execution state records where a workflow has reached; a checkpoint is an intermediate save from which the workflow can resume. It does not prove that every statement in that workflow is correct.
The knowledge base holds project documents, procedures, and specifications, each with its own versions and owners. Persistent shared memory selectively keeps conclusions that can be reused across sessions: a technical decision, a confirmed constraint, or a test result. “Shared” means that authorized agents can consult it, not that every agent can read or write everything.
LangGraph documentation distinguishes short-term memory tied to a conversation thread from long-term memory available across conversations. This is one implementation example, not a requirement to use that product. RAG can retrieve relevant passages, but retrieval relevance establishes neither the right to access a passage nor its truth.
The main decision: promote information, not transcripts
Our proposal for the portal is to save a record only when it will affect a later decision and can be checked against a source. A development agent may propose an entry, but changes affecting API contracts, security, or customer data require approval from the designated owner. A working hypothesis can instead stay with the task for a short period without entering active memory.
For example, the team decides that documents uploaded to the portal are visible only to the organization that submitted them. This is a confirmed rule if an approved specification and tests support it. A message saying “we will probably allow sharing between organizations” is merely a hypothesis. Agents building the portal must not turn it into a rule. If the portal later includes agents for end users, those agents will have separate memory governed by each organization’s access rights.
A minimal record might include the project and subject identifier, the precise statement, its type (decision, finding, or hypothesis), a source with a version or commit reference, the proposing author, the approving person, the approval date, the record version, and the review date. Provenance is the trail from the statement back to the original document or test. A link without a version may become inadequate after the document changes.
We do not store passwords, tokens, unnecessary personal data, or complete copies of confidential documents simply to make searching easier. The record can point to the authorized location of its source. Sensitive data remains in systems designed for it, with their own access and retention policies.
Who can read and change it
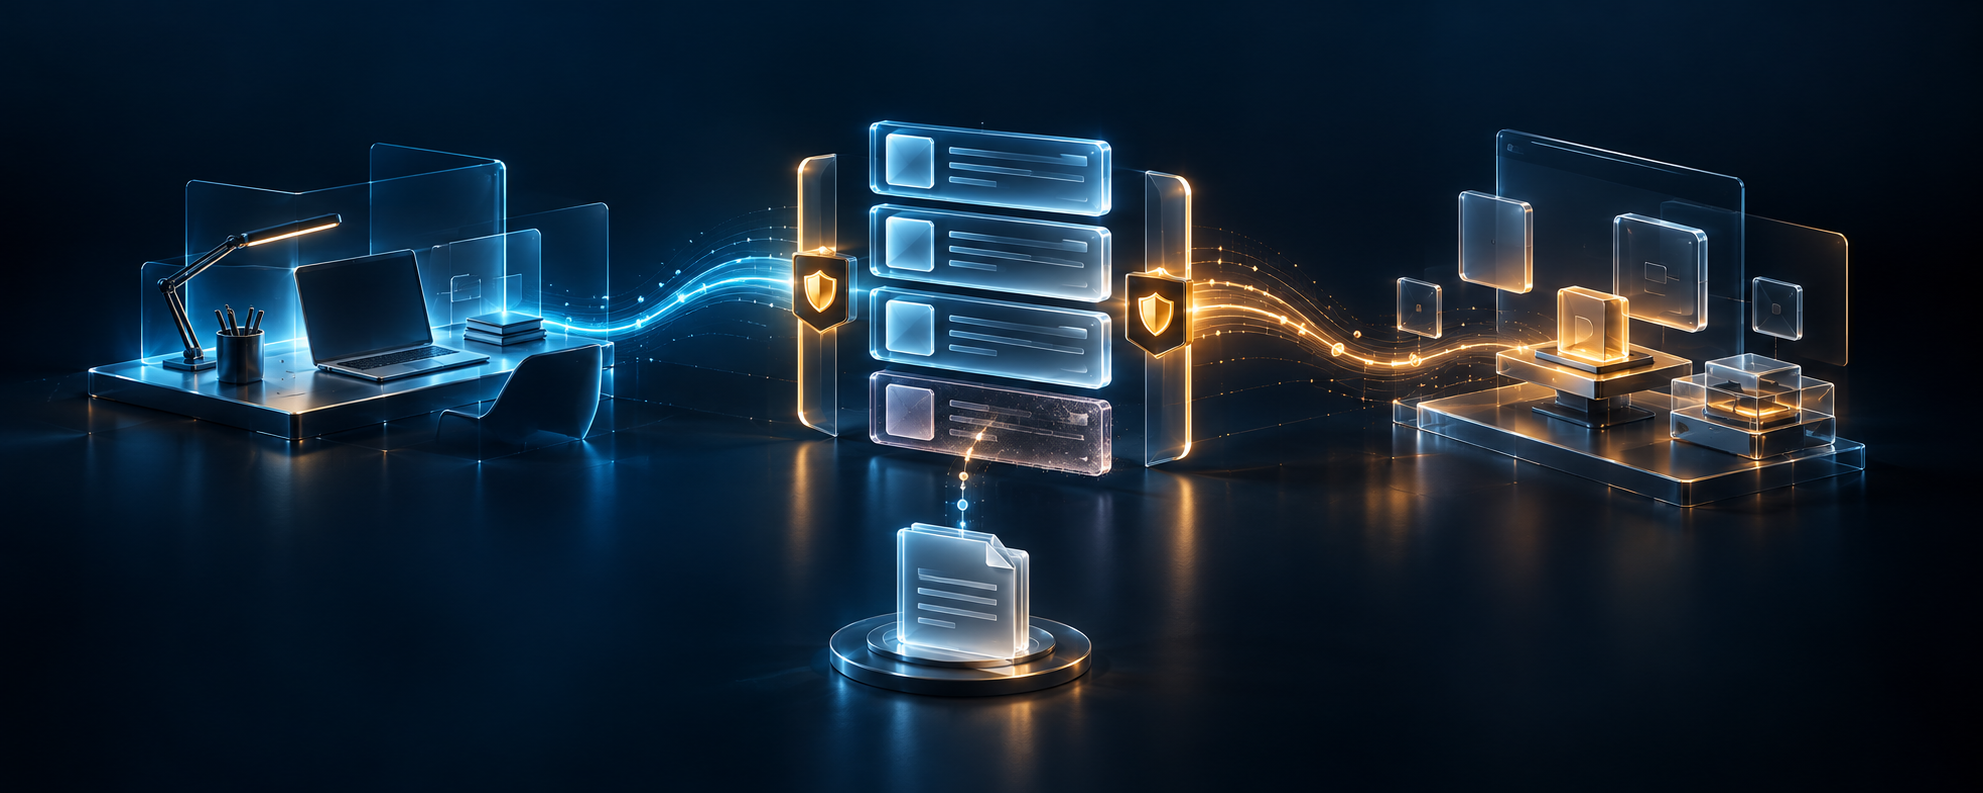
A namespace is a logical space that groups records, for example by project and organization. It helps organize data, but its name is not a security boundary. The application must check identity and permissions before each read, search, write, or deletion. In a portal serving different customers, filtering only in the agent's prompt is insufficient: the service that supplies the data must enforce access.
Agents that build the application could receive read access to project technical decisions and permission to propose new entries. Approval remains with the domain owner. An agent integrated into the portal gets permissions derived from the user and organization it serves; it does not automatically gain access to internal development notes. We log who read or changed an important record and why, according to the audit policy.
This is a design rule, not a feature guaranteed by any particular memory store. A NIST concept paper from February 2026 discusses agent identification, authorization, delegation, and action traceability. It is an exploratory document, not certification of a particular architecture. The project policy still needs implementation and testing in the chosen systems.
When two agents change the same record
Suppose one agent updates an access rule after a specification is approved while another works from an older checkpoint. Without a safeguard, the last write could restore an obsolete version. One proposed solution is optimistic versioning: the reader receives a version number, and the server accepts the change only if that version is still current. On a conflict, the agents reread the sources and request a decision rather than automatically merging incompatible rules.
Active memory points to one authoritative version of each decision. Older variants may remain in a change log for audit, but they are not given to the agent as current instructions. If a source document changes, the related record goes into review. The system does not infer validity just because the same sentence appears in several messages.
When to review, expire, and forget
Each record has an owner and a review deadline suited to its subject. A decision about an API contract is reviewed when that contract changes version; an observation about a temporary error may expire when the incident closes. The deadline need not mean immediate deletion. It means stopping automatic use until the record has been checked. Proposed states are: proposed, validated, under review, superseded, and withdrawn.
Corrections must also reach the search index, cache, and derived summaries, or an old version may reappear. Deletion from backups follows their retention policy, which is another reason to avoid collecting data that should never have been memorized. An academic preprint published in June 2026 shows that data entering through ordinary channels can contaminate an agent's persistent memory. This identifies a design risk; it does not show that every implementation will be compromised.
For our example project, the practical result is a small decision register with sources and review dates, separate from conversations and customer data. The team can start with a few manually approved records, test what each role sees, and simulate a version conflict. Only then is it sensible to automate the proposal of new memories. The next episode will use these rules to evaluate what a coding agent can actually do under the project's real conditions.